Image generation remains a future CE direction; compatible image understanding is available today.
Current integration options are documented in the API guide.
Benchmarks and Runtime Visibility are expected to expand beyond the current CE baseline.
No public timeline is implied here; CE roadmap items are direction, not release promises.
LLM Controller Pro Direction
Future Pro direction includes multi-node orchestration, distributed inference, and broader GPU scheduling for larger deployments.
Centralized coordination, expanded administration, automated benchmark workflows, and multi-system monitoring are future concepts, not currently shipping Pro promises. No public delivery timeline is implied.
LLM Controller
LLM Controller CE
About LLM Controller
LLM Controller CE brings local AI chat and model control into one browser workspace on your own hardware.
Organize conversations in Projects, work with documents and compatible images, and use optional local dictation. Review usage, runtime logs, and GPU activity where supported.
You supply compatible local models and a configured llama-server runtime. Image understanding and optional speech require their own compatible setup. No cloud AI service is required.
Key Features
Model Management: Discover, load, stop, and monitor compatible local models.
Live Analytics: Logs, GPU telemetry, token throughput, and latency metrics.
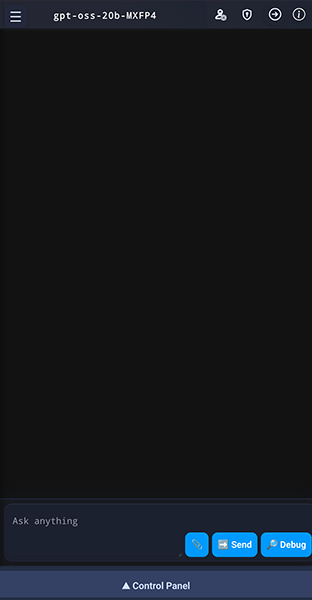
Modern Chat UI: Saved conversations, Projects, files, streaming, and reasoning display.
Local & Private: Self-hosted inference with operator-controlled access.
Actively Developed: Built to evolve with new models and features.